

Originally posted on Southleft’s blog
A few weeks back, I was talking to Christoph Hellmuth about the full range of being a Design Engineer. His background is in engineering, and my background is actually from advertising and brand. The full spectrum right there. We talk about coding capabilities but that's a totally different article. TJ already wrote his thoughts on this, he called it The Rise of the Alicorn.
With Chris we agree on what the mindset of a design engineer in 2026 is. Explore and experiment and combine different surfaces and digital material, keyword "experiment".
Experiment. verb [ I ], /ɪkˈsper·əˌment/: Actively try out new methods, ideas, or techniques to observe their outcomes.
You will need a question, a hypothesis, variables, methodology, and analysis of the output. Pretty much what he is building on his Open Design System Bench project. It's a plug-in benchmark that runs coding agents against your component library and grades the output on different axes. The high profile test involves putting agents through 3 different scenarios x 3 times each x 10 design tasks.
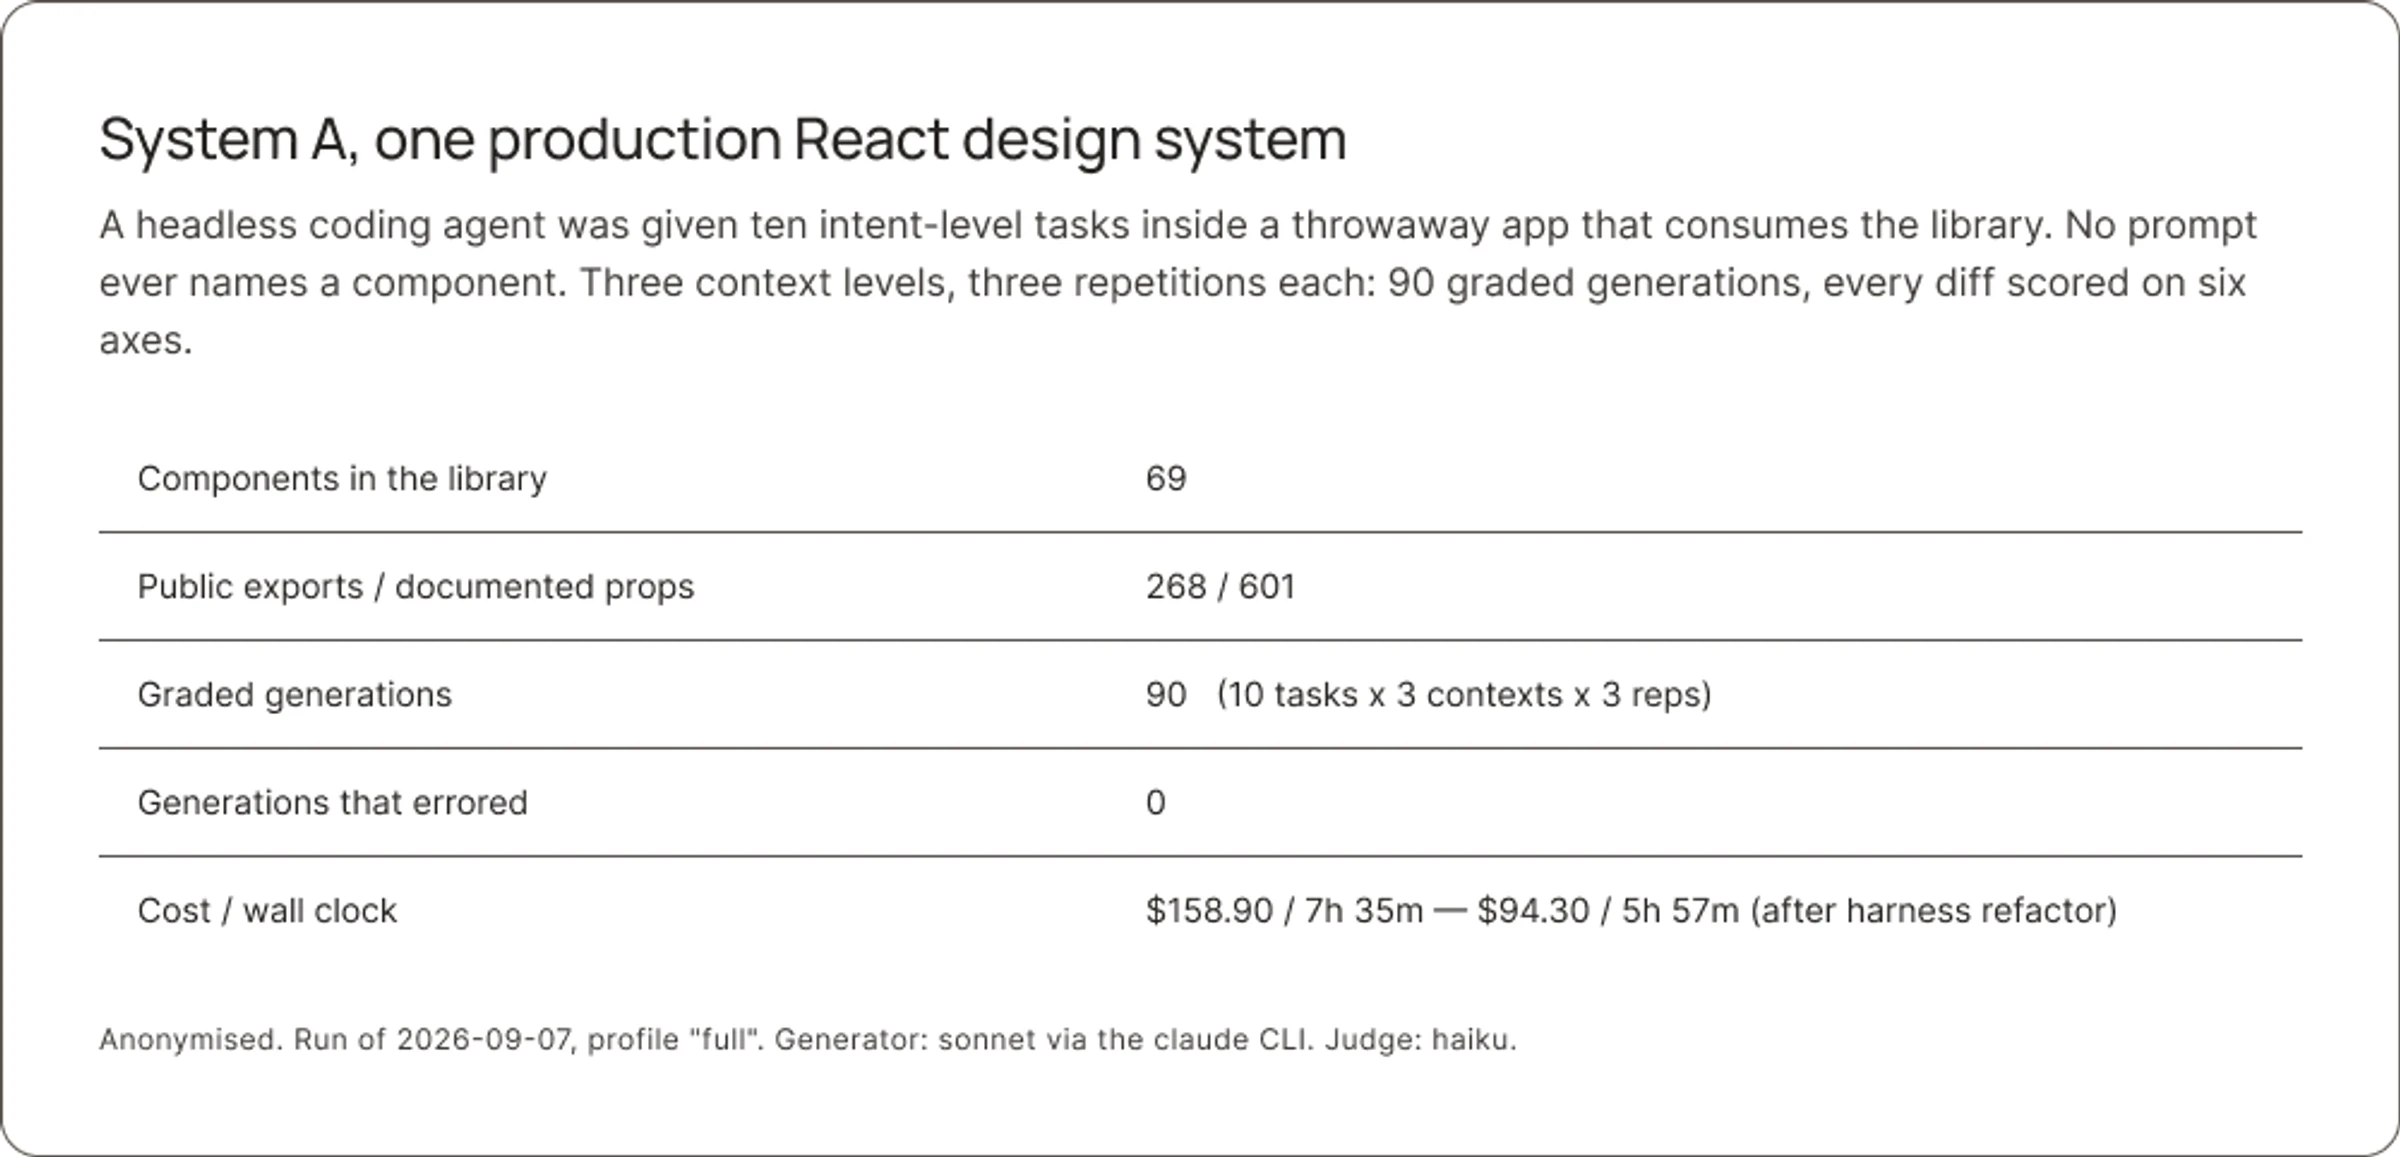
The results have been surprisingly interesting, not only surfacing components or token issues, but also validating our hypothesis at Southleft, that great engineering and design practices beats complex harnesses.
AI-readiness is about discoverability and readability
We can measure this on two dimensions, repository readiness (inside the system) and consumption readiness (outside).
Inside means how the agent can navigate your design system repo and complete design tasks. This is particularly important for your design system team. The outside dimension is about the agent using your design system properly when using tools like MCP, and/or just reading its documentation.
Grace Han posted her AI-Readiness scale earlier this year. "Traditional maturity models focused on adoption: reuse, governance, ownership, and contribution. That still matters. But AI adds another layer: Can your system be safely understood and operated by machines across functions?". Same question.
Great engineering practices beats agent harness
Let me pull back into the concept that great engineering beat harnesses. Last week we ran tests using the Open Design System Bench on a few projects. AI-readiness scored over 90 for the internal dimension, scored around 40-50 on the external. That's expected, because that's on each client team's side.
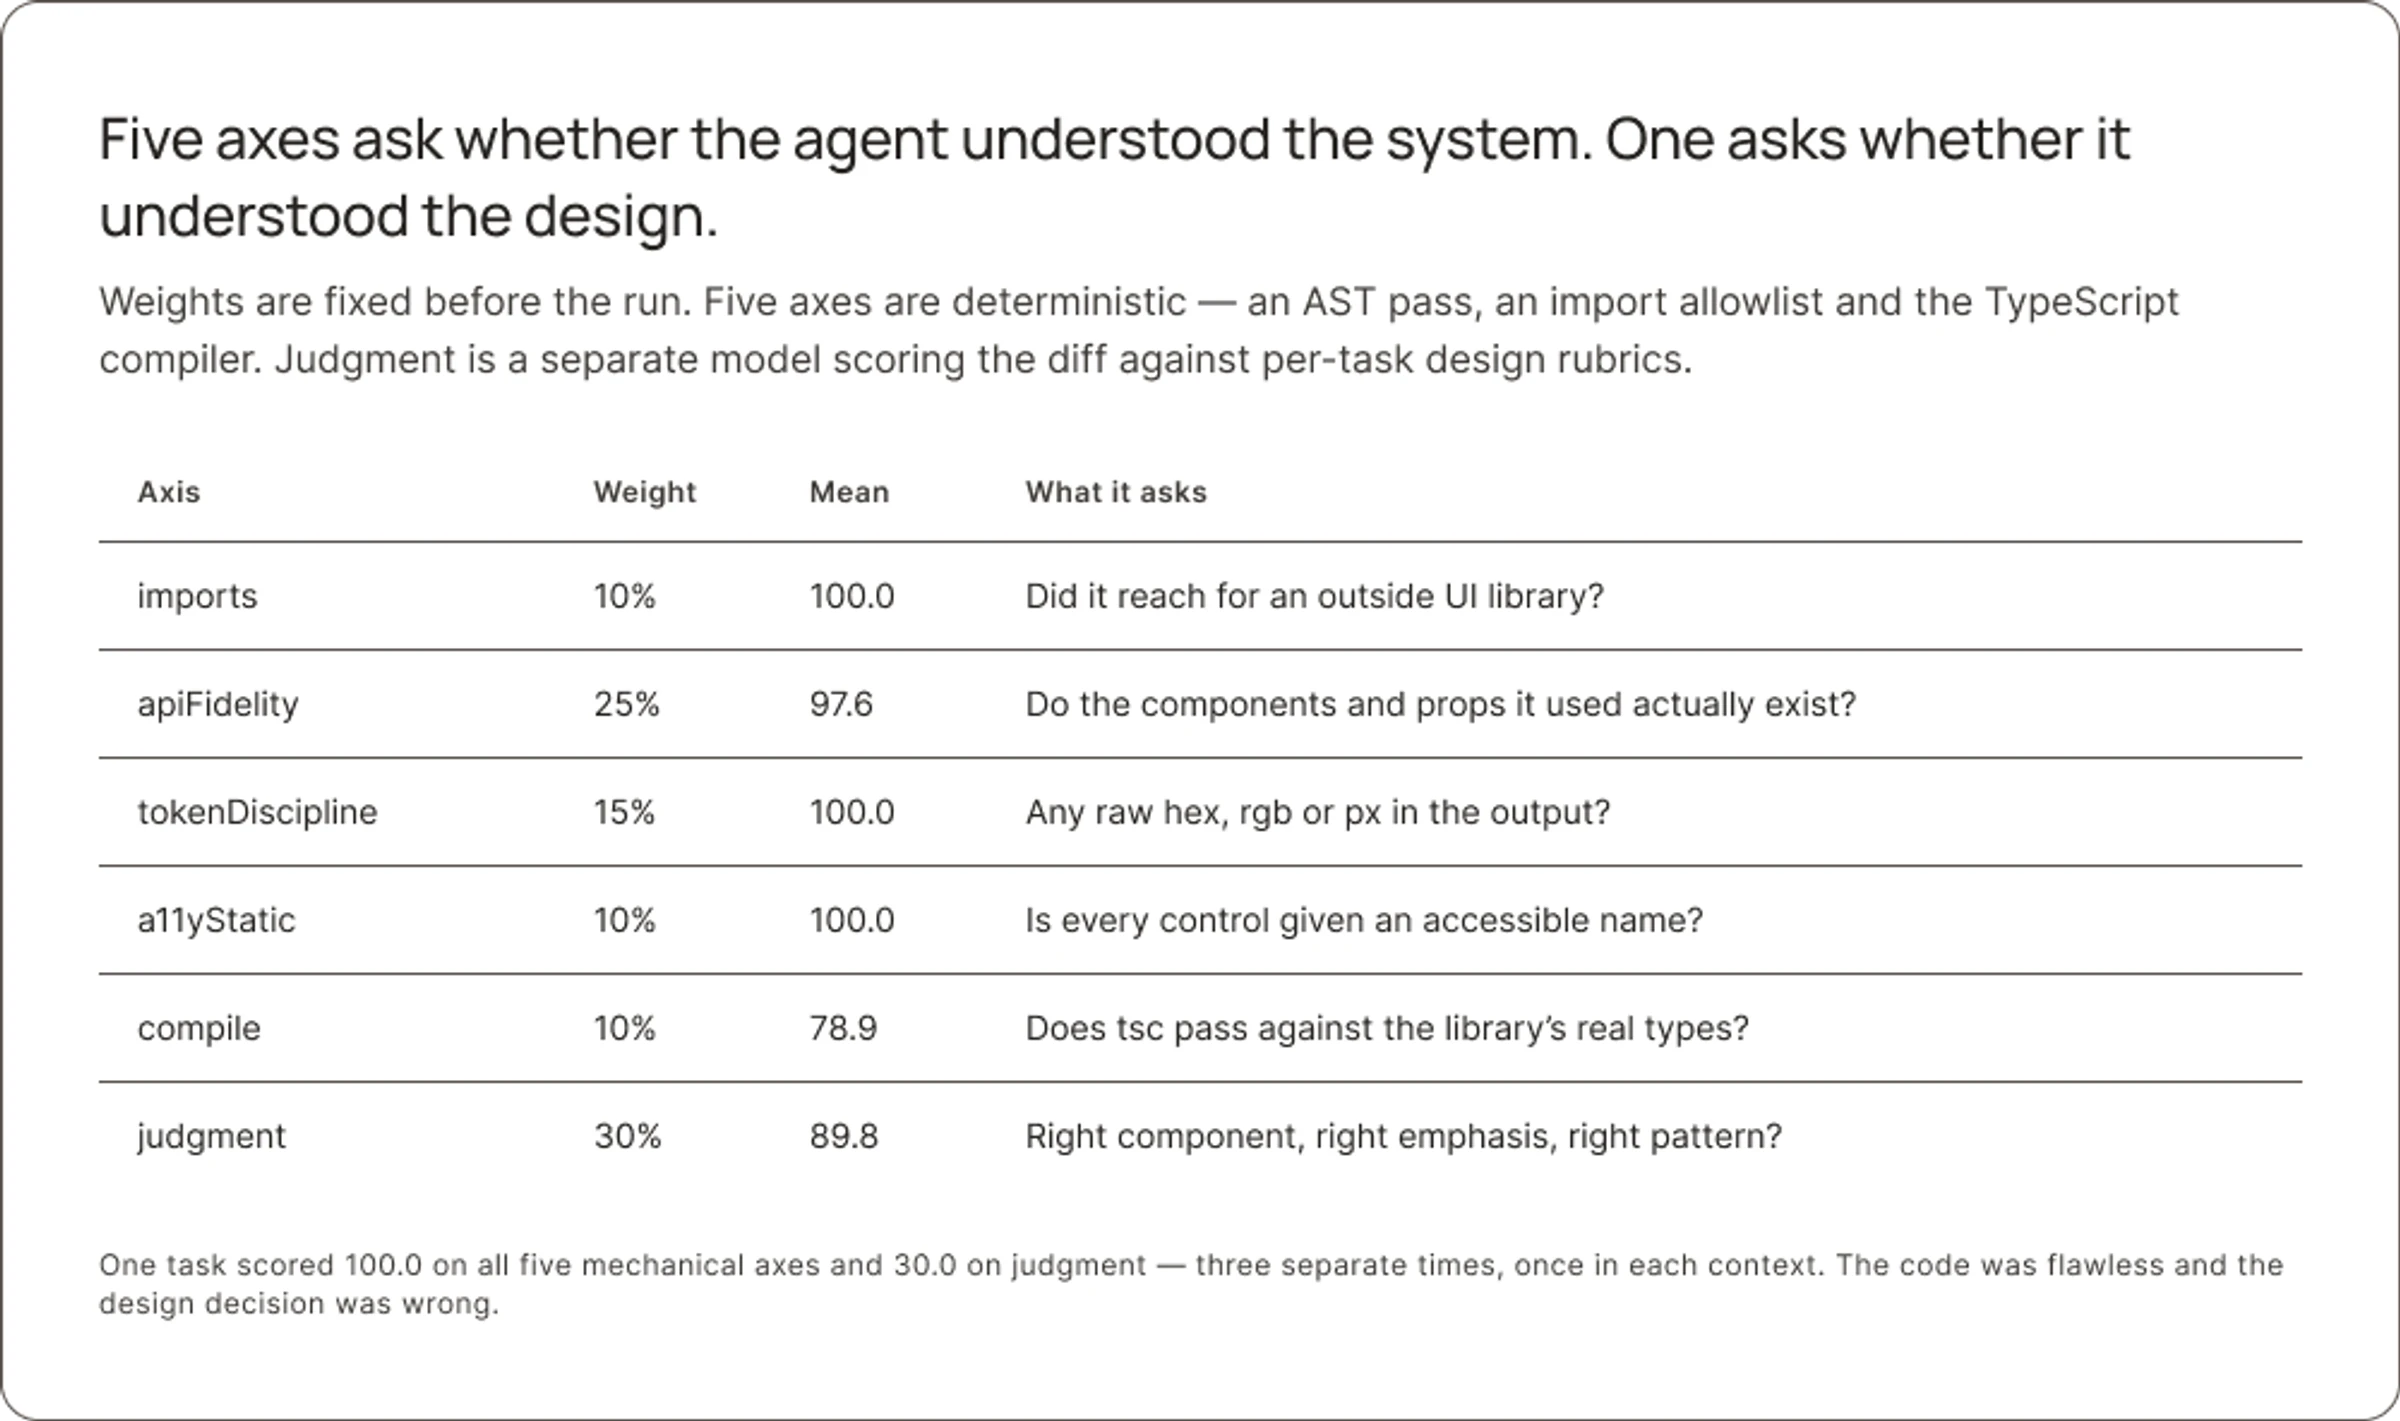
Each cell measures imports, API fidelity, token discipline, a11y, compile, and judgment. All of those are measured mechanically and are therefore heavily influenced by agent discoverability, with judgment being the exception.
How well can the agent navigate, search, find elements in your repo, and understand how everything works?
Clean code is machine-readable code
This depends a lot on two principles: separation of concerns and structured discoverability.
Separation of concerns, that means splitting a computer program into distinct sections, where each section addresses a separate, single piece of responsibility (a "concern"). This allows structured discoverability as a concept similar to Progressive Disclosure in UX, this is sequencing information and actions across several layers to avoid overwhelming the user, but for agents.
Simply put: one truth in one place. Everything else redirects to it, working as an index.
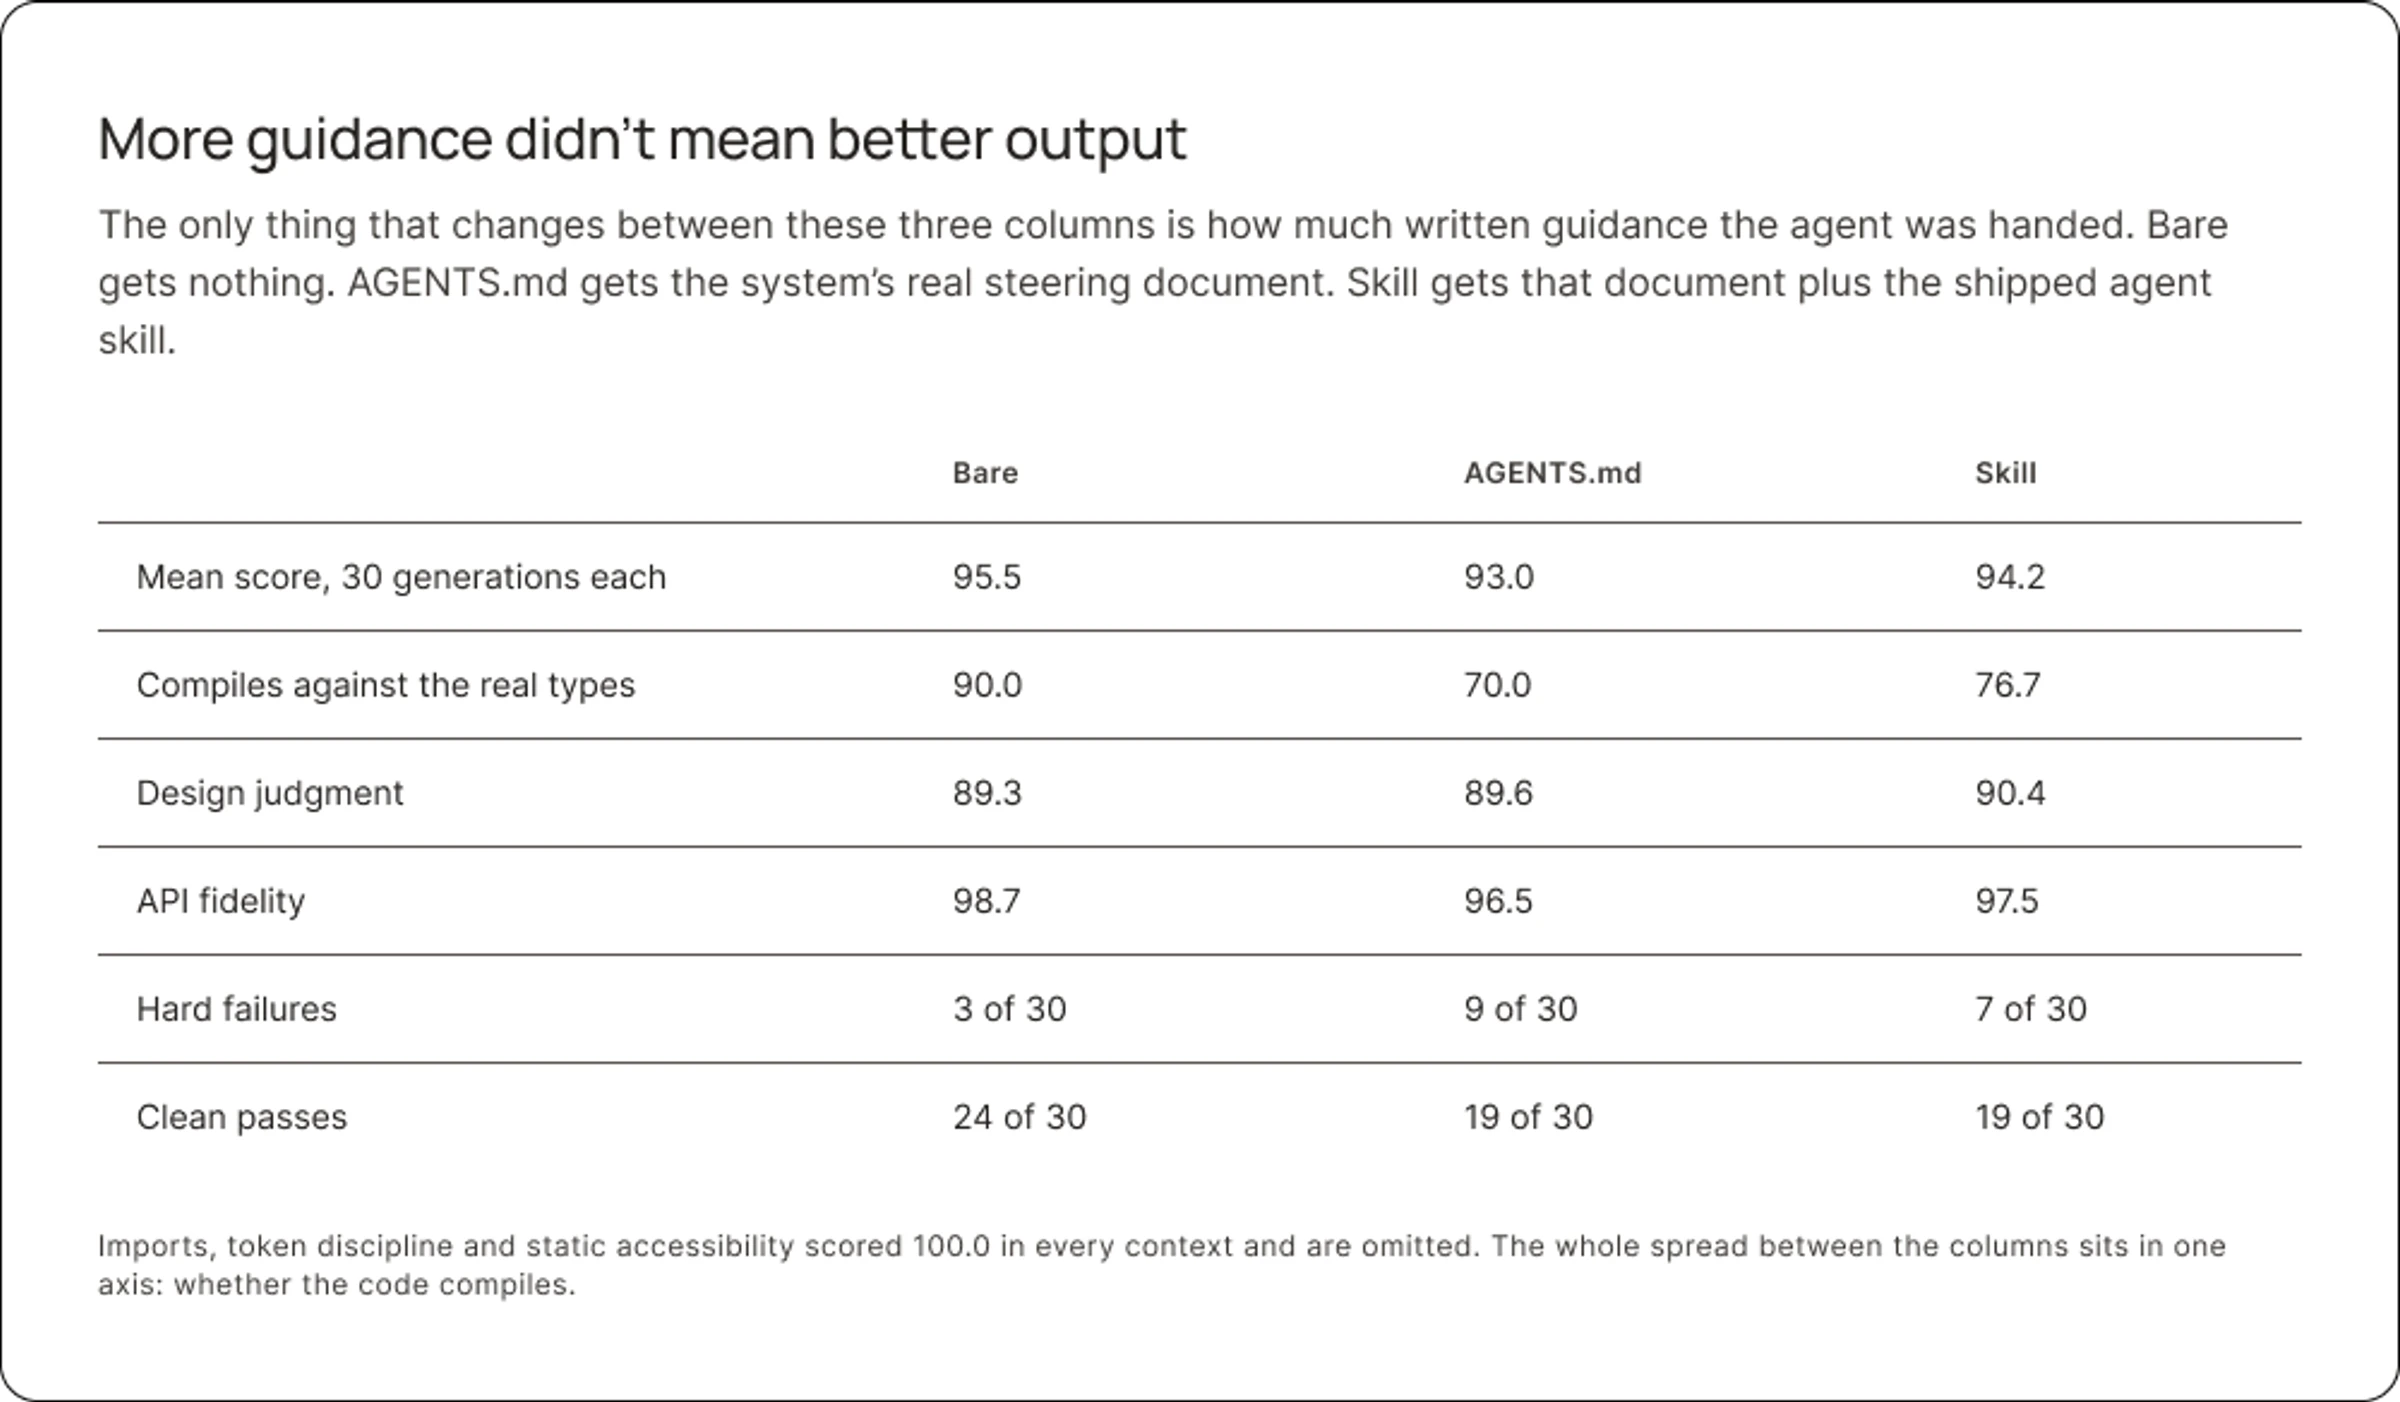
A very interesting finding is that prose files like AGENT.md, llms.txt, or whatever.md file, including agent skills can produce poor quality output by providing stale instructions. The problem is stale, duplicated, or authoritative-looking information can conflict with the source of truth. Therefore it means an additional source of hallucination. AI instructions are only valuable when they remain trustworthy.
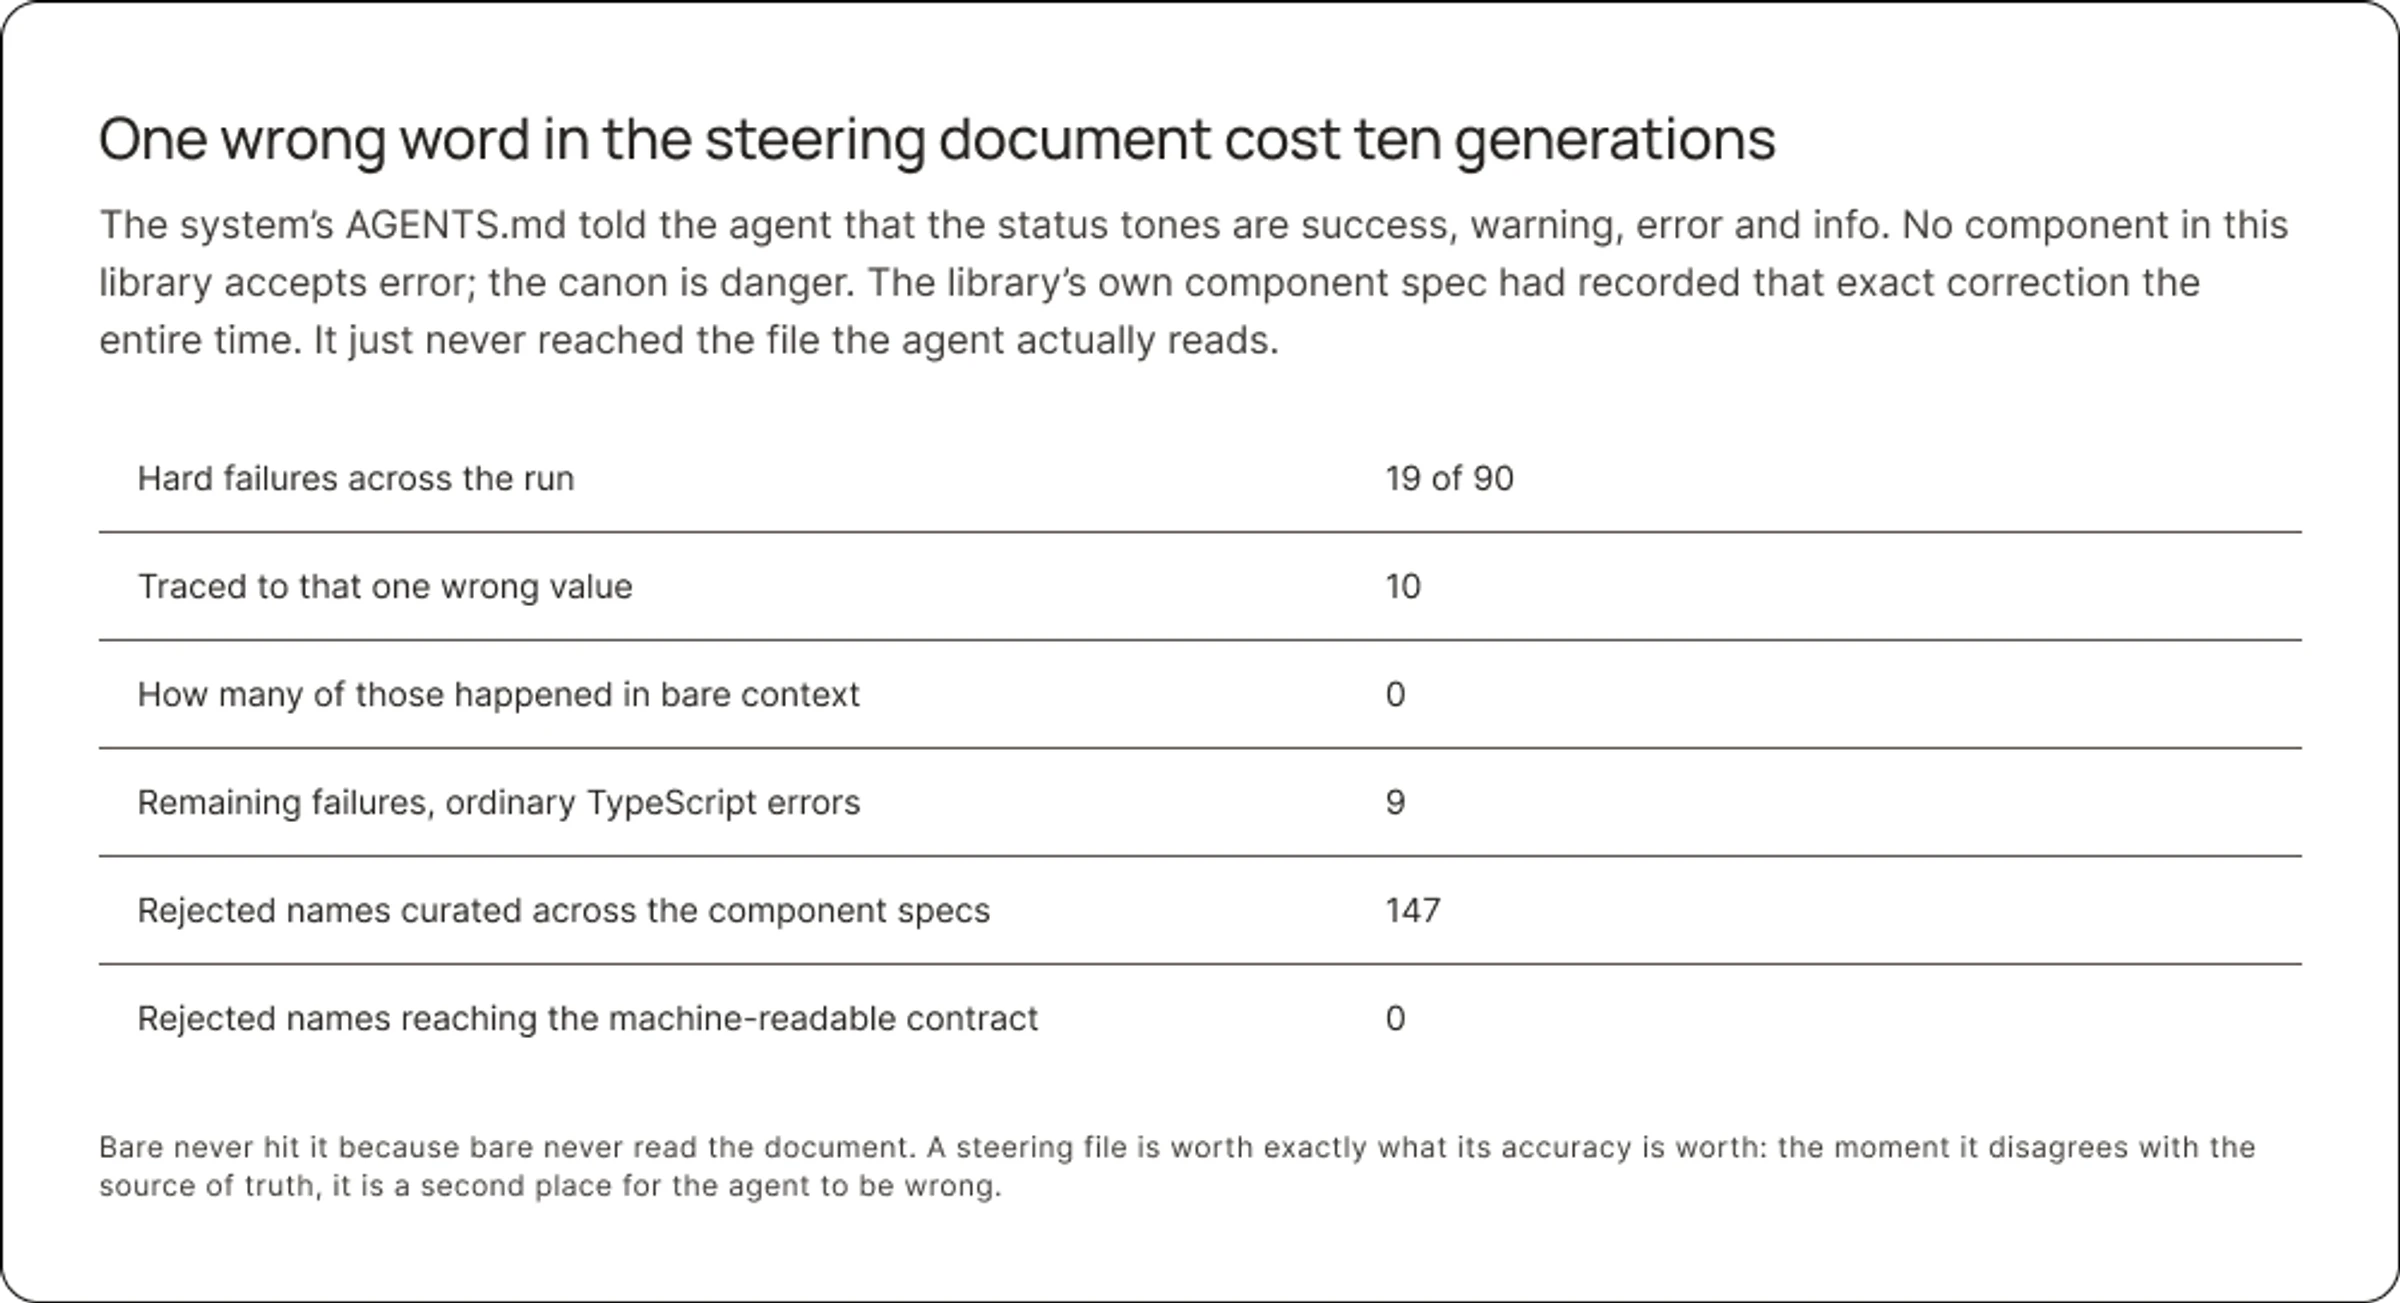
We saw bare runs (without checking harness files or skills) scoring higher. This happens mostly when hardcoding information that should be discovered dynamically, like a component or token list. The bench tasks require the agents to build specific UIs using your component library, the agent will look at those files and generate a component that already exists. Sometimes these files even hold ghost tokens, this because the agent that generated that file hallucinated.
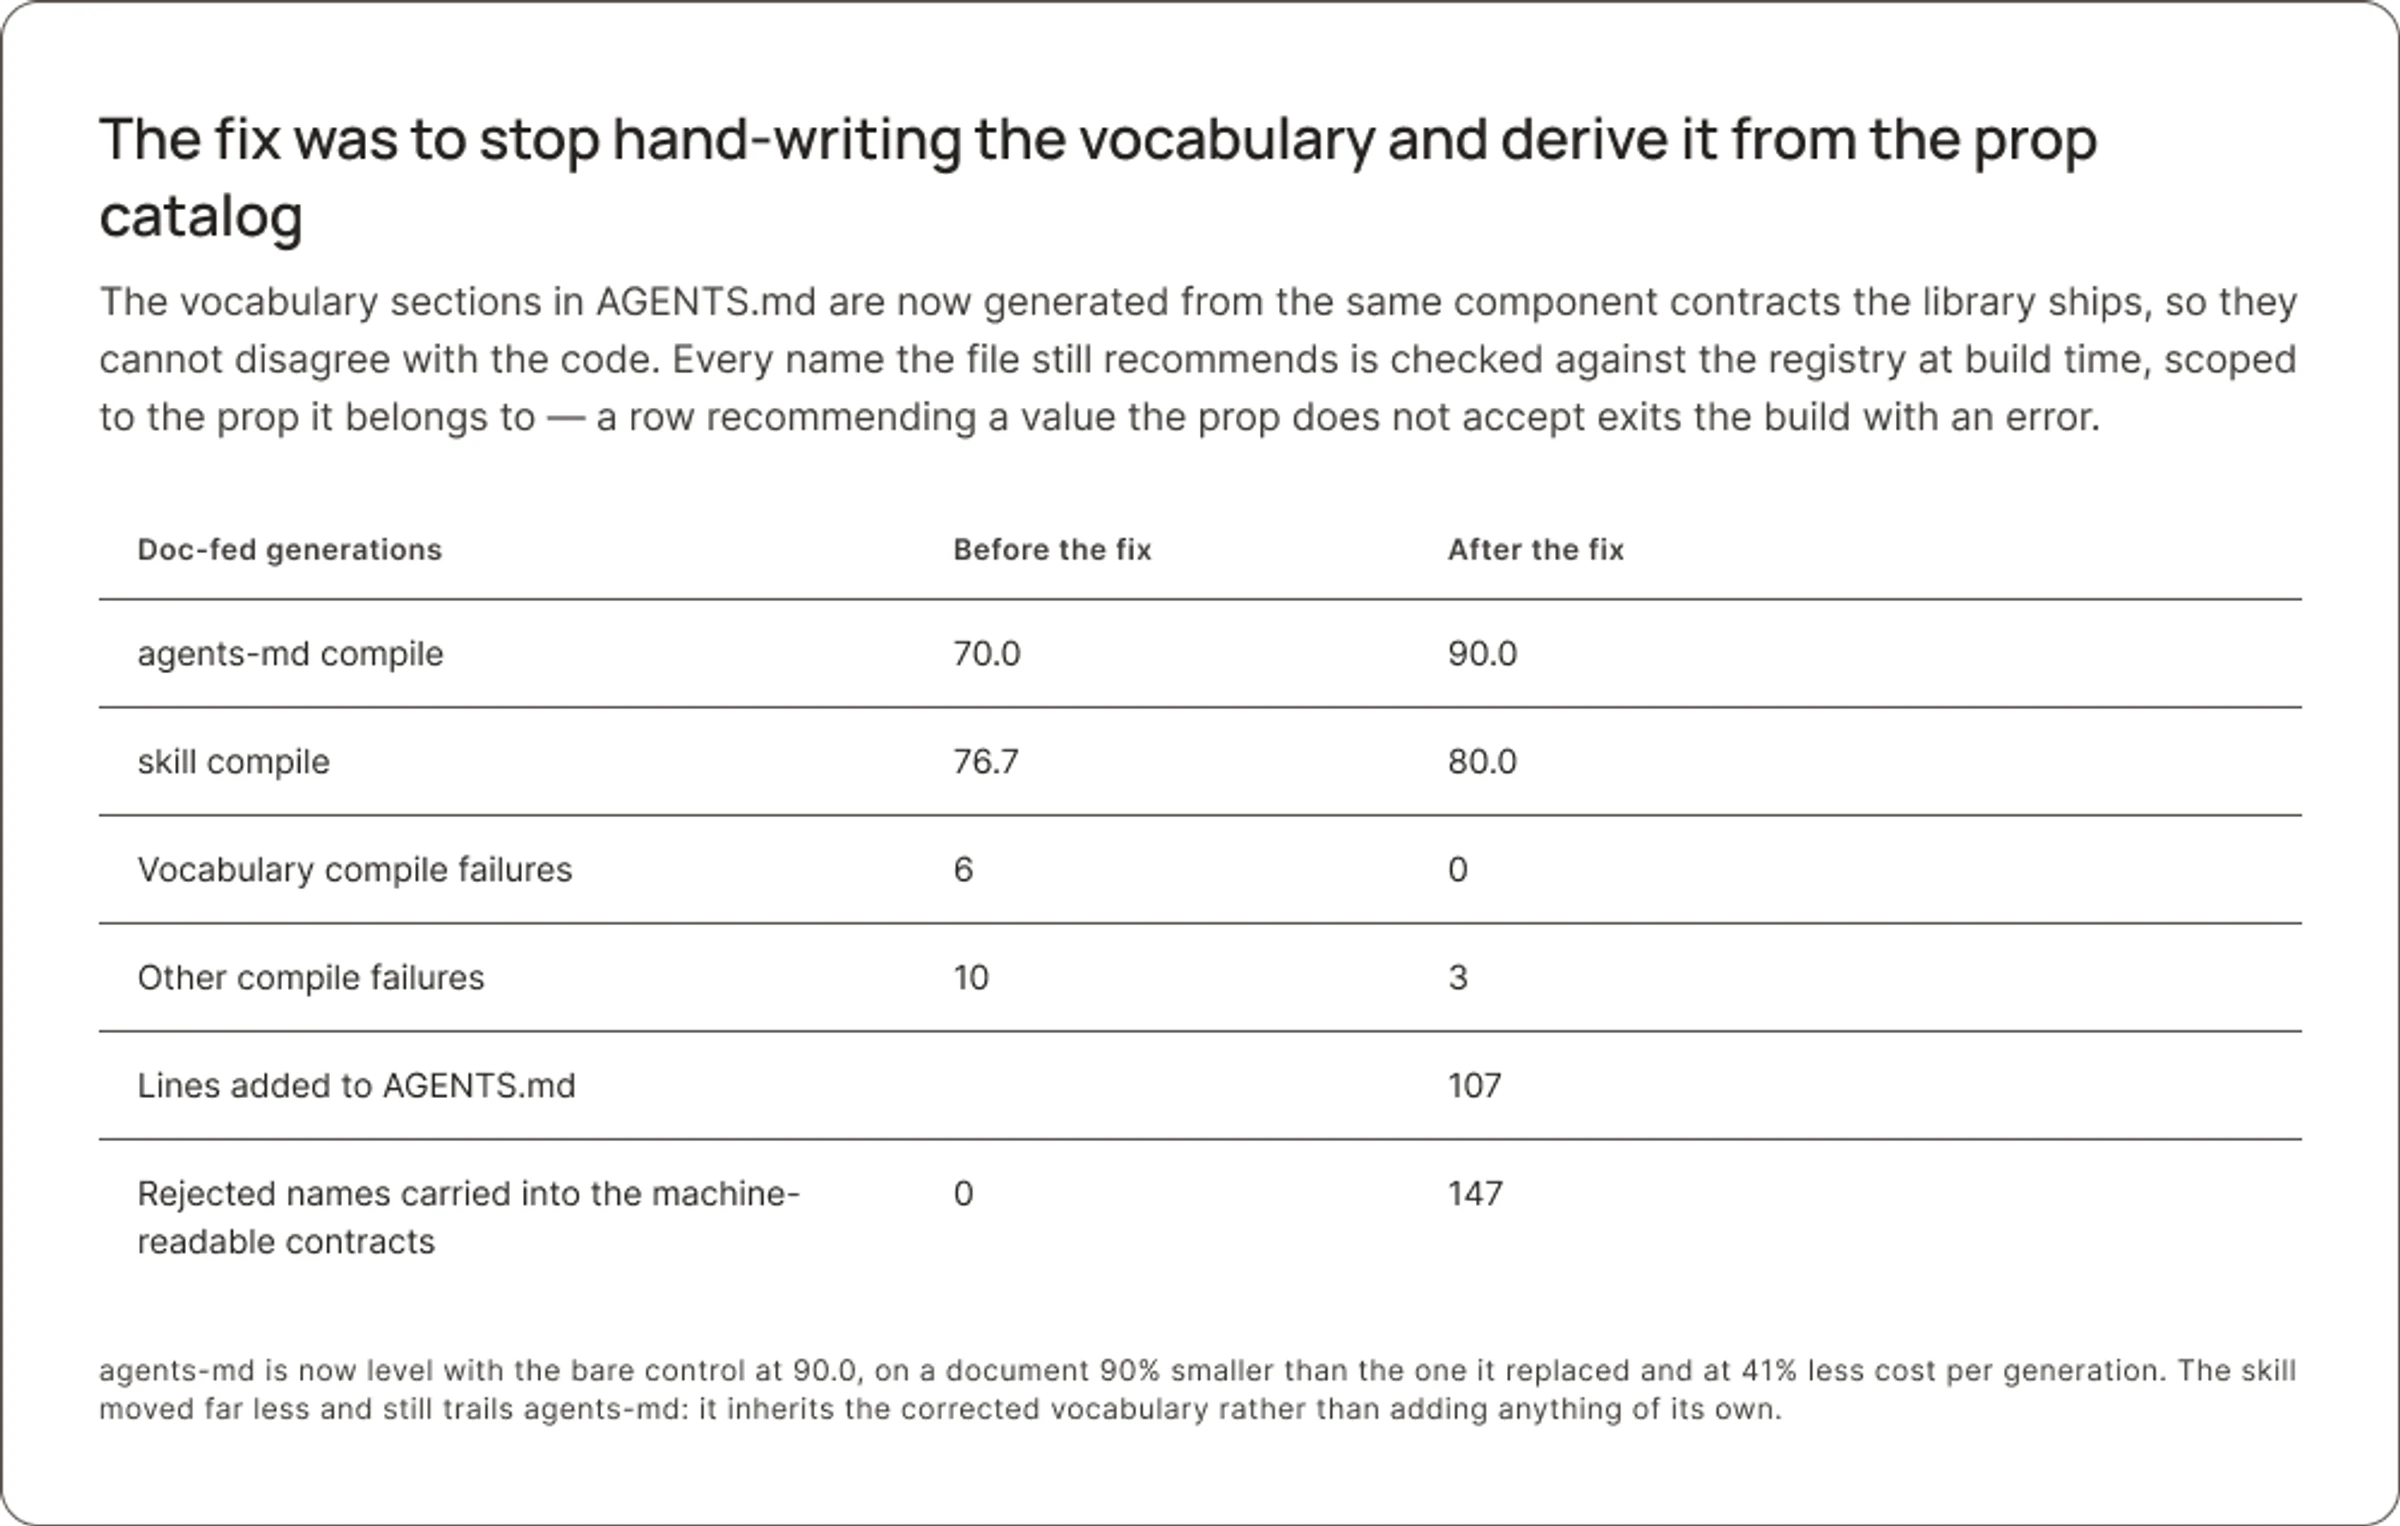
Time to put on my hard hat and refactor the whole agent harness following these principles. Added a few new docs in strategic places, and removed 90% of the AGENT.md file content. Tested again in high profile (90 cells) and to my surprise we scored lower (from 90 to 72). I totally missed we had a prop list on the file, but I knew we had the right auto-generated contract in place, just needed to point to it. Added 107 lines and improved the validation gate. Now we sit at the same 90 points baseline with a document that is 90% smaller. This also reduced the test token cost around 41%.
Judgement measures something different
Mechanical correctness ≠ design quality. Whether the agent made the right design decisions is a completely different beast. Was that the correct component for the intent, correct emphasis hierarchy, correct interaction pattern. This is different from whether the code compiles or the API is used correctly. It's totally possible to score 100 on the mechanical dimensions and score 26 here. We know that, because it happened to us.
Mechanical dimensions tell us whether the agent understood the system. Judgment tells us whether it understood the design.
Here is where agent instructions and skills shine, these should be focused on design language. Don't give agents a list of answers. Give them the language and principles they can use to arrive at the right answer. A good example of this is Vercel's DESIGN.md, that's actually more like a brand guideline than other examples of this file found on the web. To build a file like this you should put on your scientist coat and run evals (lots of them).
If judgment is the difficult part, you can't improve the guidance without evaluating the outcomes. A good starting point is reading Teresa Torres's article on AI Evals: A Hands-On Guide for Product Teams. Vercel published an article on the methodology they used for building their DESIGN.md file.
Going deep into this means scoring higher on the external dimension of the test. There are different strategies on how to expose data from your design system through open knowledge-bases, MCPs and custom internal tooling.
Do AI-Ready, AI-Native, Agentic or similar prefixes hold in the future?
Probably not. Just like we stopped saying "Mobile-Friendly" because everything is just expected to work on mobile now. TJ revisited his view on Context-Based Design System and Use AI to Need Less AI.
Optimize for being a great design system. Then AI-readiness emerges as a property of that system. It's a new way of exposing whether the quality bar you've already set is actually being met.
The best practices to build them using great engineering, design and governance models will do. That's what we do at Southleft, we keep moving forward and experimenting in the space, pushing the relationship between AI and the humans in the loops.
If you're working through this on your team and want to compare notes, we'd love to talk. The conversation is more interesting than the discourse.